Four sites we measured.
Not case studies. Four real runs of an earlier build of the engine you get: two public sites by name, two of our own, said for what they are. The findings counted by severity, and the score that came out.
Four sites, one instrument Measured
The same shape four times, so they can be compared at a glance: the score, and every finding drawn as one mark, coloured by severity. The table underneath has the same numbers written out.
Four runs · written down 3 Sept 2026
pypi.org
50/100 · 19 findings
- 2 high
- 6 medium
- 4 low
- 7 notes
Our own previous site
41/100 · 16 findings
- 1 critical
- 3 high
- 4 medium
- 4 low
- 4 notes
example.com
28/100 · 39 findings
- 6 high
- 13 medium
- 13 low
- 7 notes
Our deliberately broken test site
21/100 · 44 findings
- 1 critical
- 9 high
- 13 medium
- 14 low
- 7 notes
All four were written into our test suite on 3 Sept 2026, from runs of the engine as it stood then. It has gained rules since, and it counts differently: run again on 1 Oct 2026, our deliberately broken test site scores 23/100 with 48 findings and no critical, where the table says 21, 44 and 1. The critical went because the engine now files plain http on a local test address as a note — an address like that cannot hold a certificate — so that is the engine changing, not the site being fixed. We have not run the other three again.
The same four, written out
| Site | Score | Findings | Critical | High | Medium | Low | Notes |
|---|---|---|---|---|---|---|---|
| pypi.org | 50 | 19 | 0 | 2 | 6 | 4 | 7 |
| Our own previous site | 41 | 16 | 1 | 3 | 4 | 4 | 4 |
| example.com | 28 | 39 | 0 | 6 | 13 | 13 | 7 |
| Our deliberately broken test site | 21 | 44 | 1 | 9 | 13 | 14 | 7 |
“Findings” is the five severity counts added up — critical, high, medium, low and notes. Notes are the lowest severity and weigh nothing in the score.
What a finding actually says
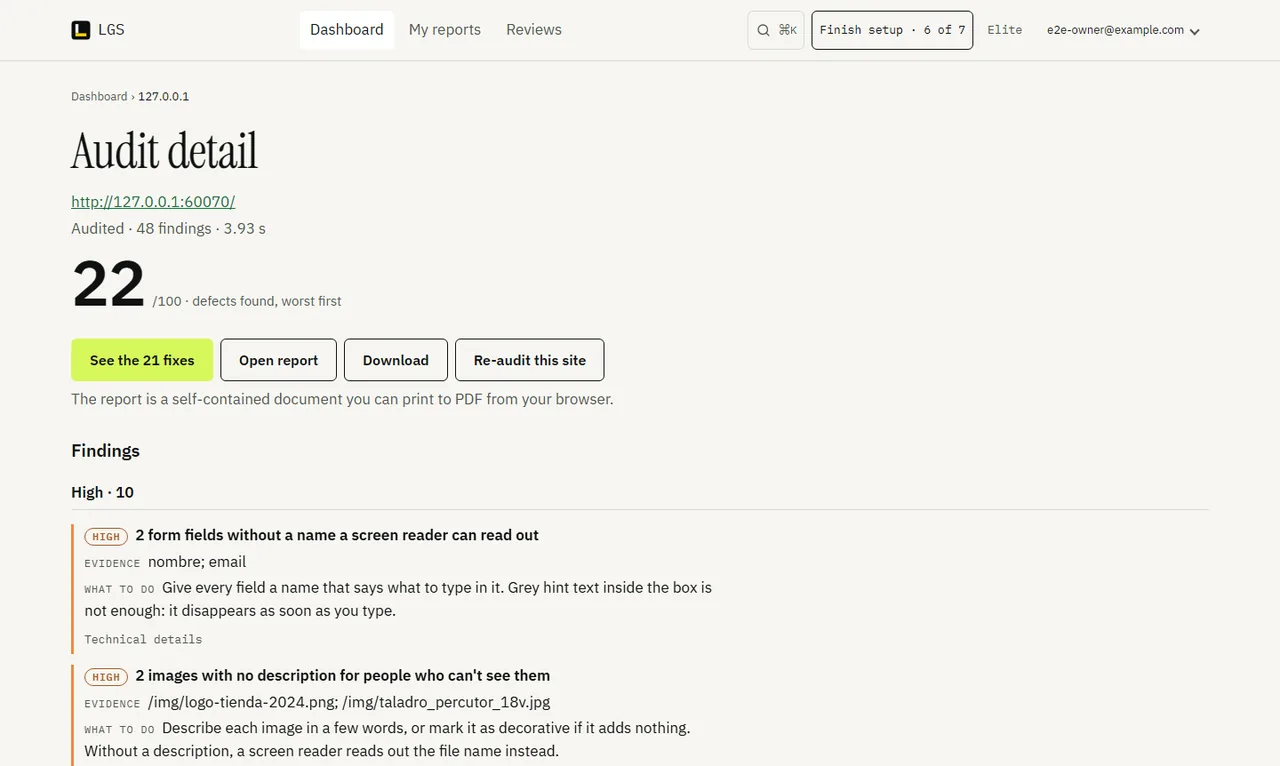
This list is from a different run, not one of the four above: the recording of a fictional Hawthorn plumber’s site that the homepage replays. That site is an English copy of our broken test site with the same faults planted one by one, so its findings echo the report further down. The ten worst findings in it, with their real titles, not examples.
Recorded run · a fictional Hawthorn plumber’s site
The ten findings are listed here when JavaScript is on.
The report itself
Worst first, with the evidence quoted and what to do in plain English. This is the screen, not a mock-up.
What these numbers are, and what they are not
They are real. Every row is a run of this engine, and the breakdown is copied from the report’s own summary. They are checked by a test in our repository, so this page cannot quietly drift away from what was written down.
Two of the four are ours. One is the site this company used to run — it scored 41, and it had a critical. The other is a test site we broke on purpose. We show ours because a page of other people’s bad scores proves nothing about whether we are honest about our own.
They are not Melbourne tradies. These four were measured while building the engine, not gathered as customer testimonials. We are not going to relabel them as local businesses to make the page read better.
The score counts issues, not quality. It is a weighted count of what we found, so a critical finding costs as much as thirteen low ones. No number of rules turns a subtraction into a judgement.
The only run that matters to you
Is yours. The trial runs it, within a fixed number of audits for seven days. Card on file, nothing charged until day 8, and you cancel from the dashboard at no cost.